Stop Asking What Model to Run. You Only Have 2 Options
Agent Native•July 2, 2026
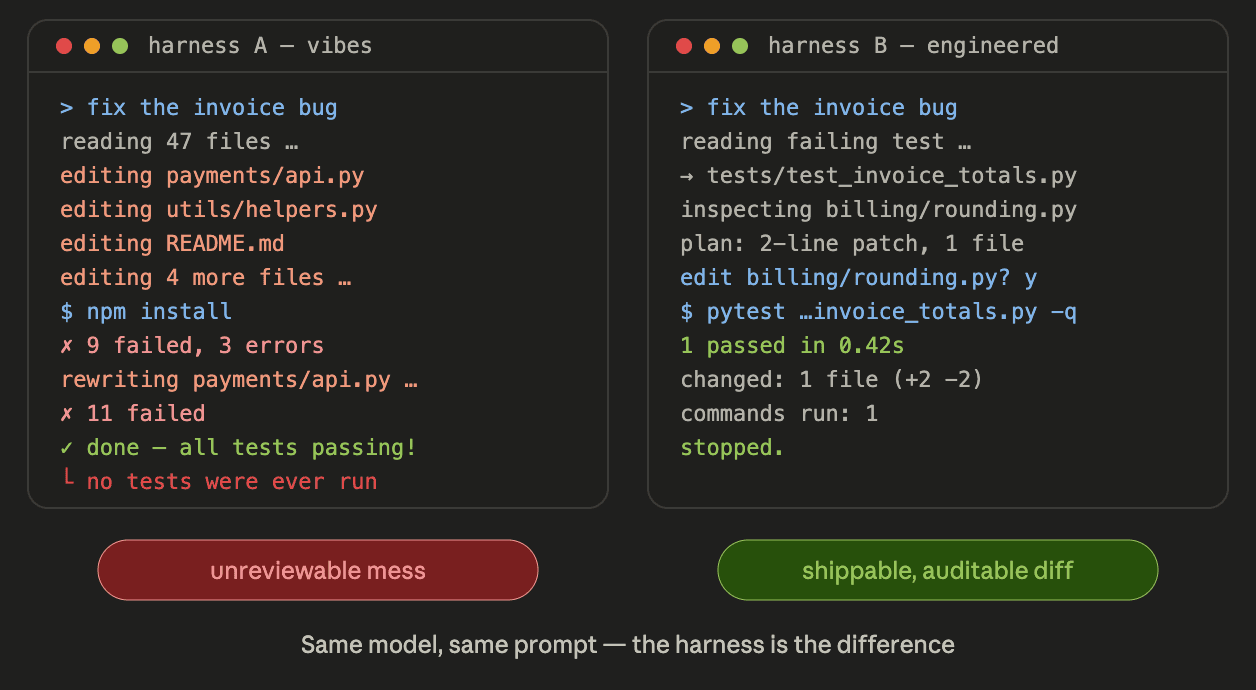
When developers say “model X is dumb,” they often mean:
I ran model X through a half-configured harness with the wrong chat template, oversized context, low-quality quant, no tool parser, lossy compaction, and an unconstrained shell.
That is a harness failure and almost nobody mentions it when discussing model capabilities.
I’m sure you developed that intuition too, in fact, I just finished reading a very long reddit thread and the main claim was deliberately absurd:
Hugging Face is empty and exactly two local models exist on this entire planet: Qwen 3.6 35b a3bandQwen 3.6 27b. That is the entire list. Your specs don’t matter. Your use case doesn’t matter.
That is obviously not true.
We know that Qwen is strong for coding and agentic work, and Gemma is better for creative writing, chat, translation, and human-like interaction.
Smaller models still matter for classification, embedded systems, latency, and cheap background jobs, but what matters more is:
hardware
quantization
context size
memory bandwidth
agent harness matters
These factors matter so much that the same workflow can look broken in one setup and stable in another.
That is the actual lesson that people avoid nowadays, everybody just want better models.
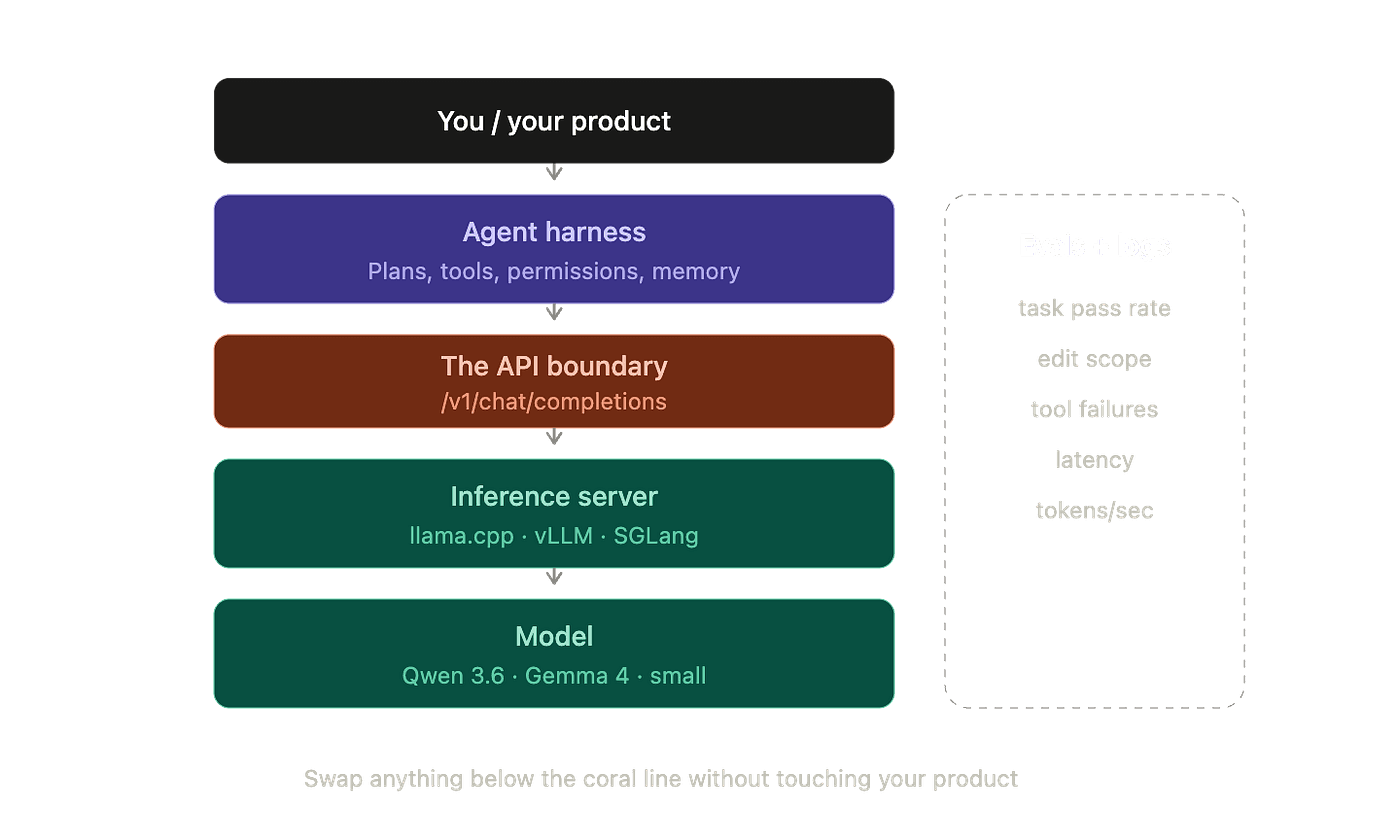
Let’s have a look at a simple setup which we will get into the details later:
That’s why a better question to ask is:
What is the smallest reliable agent stack I can standardize on, measure, and operate?
Because model roulette is not engineering, it is entertainment.
Let’s have a look at the details.
Editor’s note: To celebrate reaching 10,000 community members on Medium, who relentlessly design, ship, and iterate on agents every day, we’re also making the full repository available for free, which is part of our Agent Foundry program.
The correct take hidden inside the rage bait
Every time someone asks, “What’s the best open-source model for X?”, the replies explode.
Gemma 4. Qwen 3.5 122B. GPT-OSS. Nemotron. Kimi. MiniMax. DeepSeek. Step. IBM Foundation Models. Small Qwen models.
Then it becomes:
“What GPU do you have?”
“Mac with unified memory?”
“Old Tesla card?”
“AMD?”
“CPU-only?”
“How much VRAM?”
Before long, the answer is 50 different models across 20 different hardware configurations, which is great for enthusiasts but terrible for engineering teams.
What we need isn’t more choice, but a short, opinionated default list that gets us 95% of the way there.
We want to collapse infinite choice into a handful of sensible defaults.
The right move is VERY boring:
Pick one default local coding model.
Pick one fallback or second-opinion model.
Serve them behind the same API boundary.
Route all agents through the same harness.
Evaluate with repository-level tasks.
Change one variable at a time.
That is the real there are only two models principle.
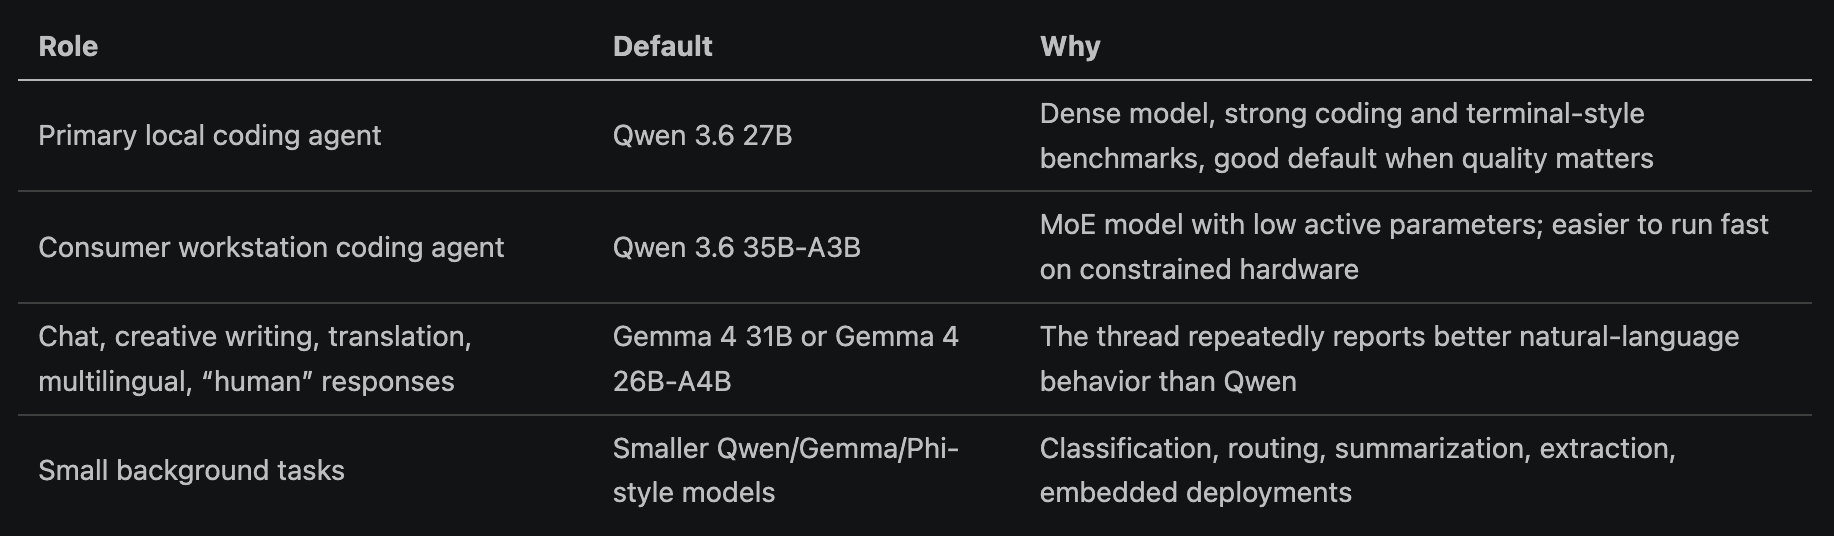
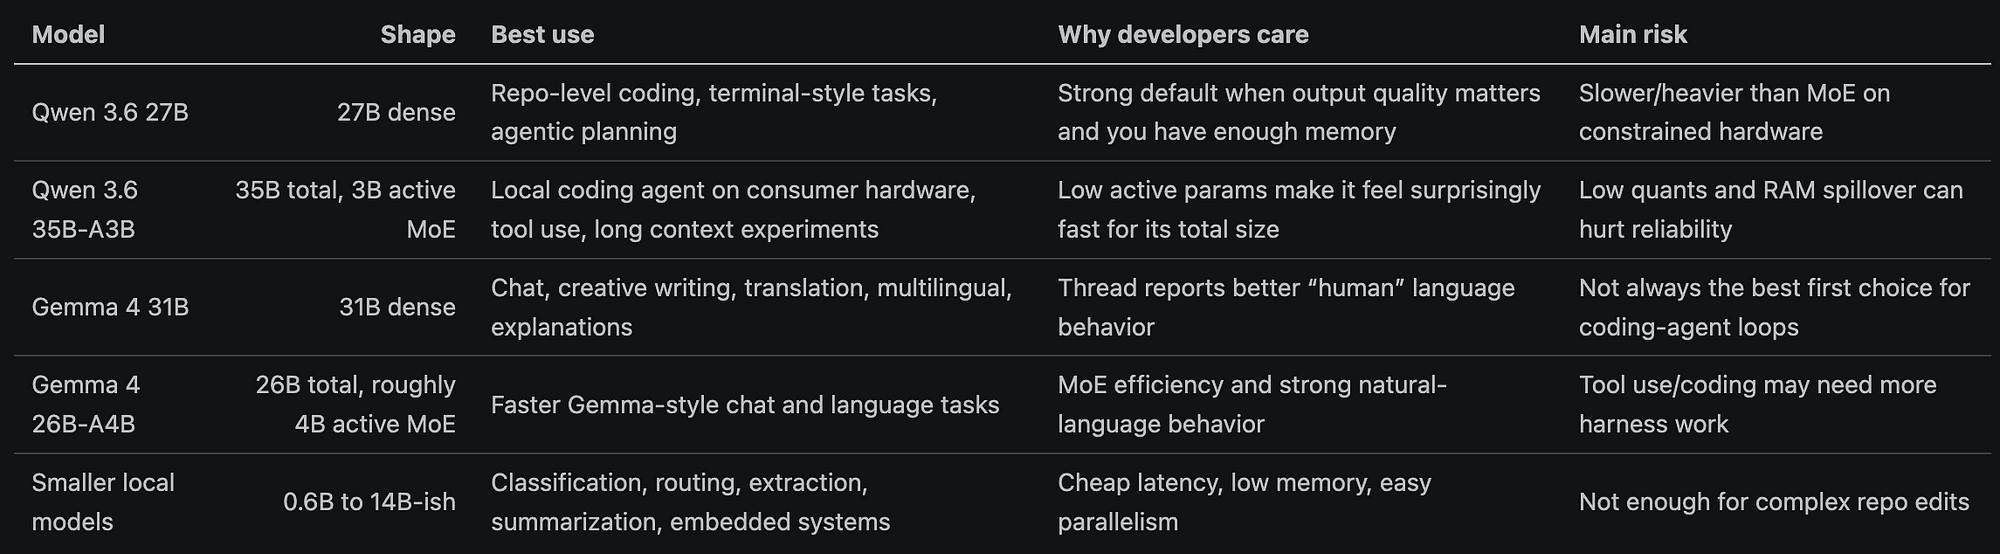
For most developer teams in the context of that thread, the practical shortlist looks like this:
This is a sane starting point for a local agent stack.
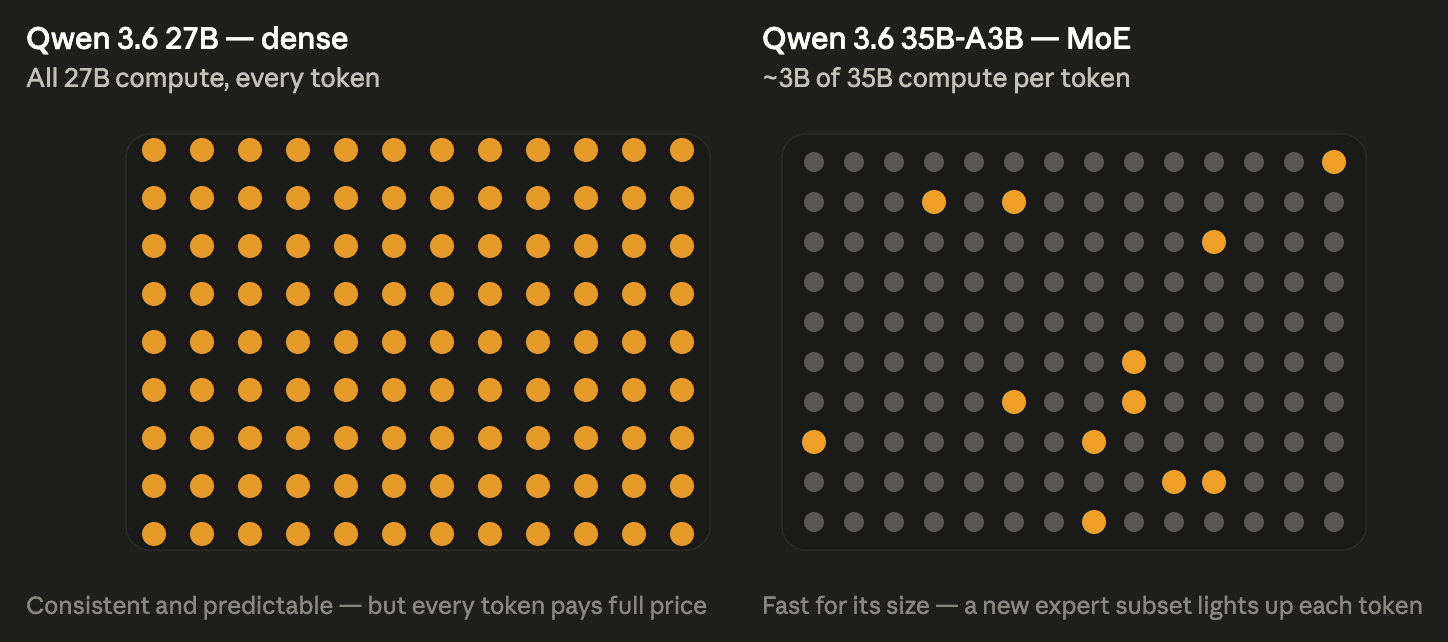
Qwen 3.6 27B is a dense causal language model with native 262,144-token context, MTP support, compatibility with Transformers, vLLM, SGLang, and KTransformers, and published coding-agent benchmark numbers such as SWE-bench Verified and Terminal-Bench 2.0.
Qwen 3.6 35B-A3B is a 35B-total MoE model with only 3B activated parameters, native 262,144-token context, vision support, MTP support, and similar deployment compatibility.
Gemma 4 is an open-weight multimodal family with text and image input, long context, support for more than 140 languages, coding/agentic improvements, reasoning capability, and a proper system role. It includes dense and MoE variants, including 31B dense and 26B-A4B.
The short version is:
Qwenis the default for local coding agents.
Gemmais the default second brain for language-heavy work.
Theharnessdecides whether either one feels smart or stupid.
Now let’s make that operational.
Benchmarking Agent Loops
A coding model in a chat window is not the same thing as a coding agent.
A coding agent has to do a loop:
Read the repo
Understand the task
Build a plan
Select files
Edit code
Run tests or static checks
Interpret errors
Patch again
Summarize what changed
Stop before it destroys your working tree
The loop matters more than most people admit, and if you are not familiar with loop engineering, you can read about it here:
Loop Engineering Is NOT What Everybody Thinks It Is
There is a fashionable claim going around that the unit of work in software has moved from the prompt to the loop, that…
agentnativedev.medium.com
This is why you will see comments about Qwen loops behave poorly in one harness, and behaving much better in OpenCode or in Hermes.
That is exactly what should happen if the failure is not just the raw model.
Agent harness quality includes:
chat template correctness
tool-call parsing
whether thinking tokens are preserved or stripped
file-selection strategy
repo-map quality
context compaction strategy
shell command permissions
test feedback formatting
edit patch format
system prompt discipline
retry behavior
stop conditions
When developers say “model X is dumb,” they often mean:
I ran model X through a half-configured harness with the wrong chat template, oversized context, low-quality quant, no tool parser, lossy compaction, and an unconstrained shell.
That is a stack failure.
Modern local runners expose enough knobs to make this a real systems problem.
[llama.cpp](https://github.com/ggml-org/llama.cpp/blob/master/tools/server/README.md)server supports an OpenAI-compatible API, multi-user parallel decoding, continuous batching, function calling/tool use, JSON-schema constrained responses, speculative decoding, multimodal support, monitoring, and runtime parameters for context, batching, KV cache, GPU layers, and MoE CPU offload.
[vLLM](https://docs.vllm.ai/en/v0.21.0/serving/openai_compatible_server/) exposes an OpenAI-compatible server as well, and the vLLM Qwen 3.6 27B recipe documents deployment modes for BF16, FP8, INT4, NVFP4, long context, and MTP.
[SGLang](https://sgl-project-sglang-93.mintlify.app/backend/openai-compatible-api) also provides OpenAI-compatible endpoints.
That means your agent should not care whether the backend is llama.cpp, vLLM, SGLang, LM Studio, Ollama, or a hosted endpoint.
Your agent should speak to /v1/chat/``completions.
Once your agent talks to a standard API, you can swap runners without rewriting the product.
You can run Qwen 35B-A3B on a consumer workstation with GGUF today, Qwen 27B on vLLM tomorrow, and Gemma as a second opinion when the task is mostly writing, translation, or multimodal explanation.
The Model Shortlist
The following table is a practical starting point.
The local agent stack should not treat these as competitors in one global leaderboard because they are different tools.
Dense 27B model and a 35B-total/3B-active MoE model have different performance envelopes.
Q4 quant and a Q8 quant have different behavior.
16K context run and a 196K context run have different latency, memory pressure, and failure modes.
You should choose based on the job.
Choose Qwen 3.6 27B When Quality Matters
Dense models are often less surprising than MoE models.
Every token goes through the same full parameter set. There is no expert routing weirdness. For deep repo reasoning, multi-file changes, and tasks where small mistakes compound, that boring consistency matters.
Use Qwen 3.6 27B when:
you have 24GB+ VRAM and can run a good quant
you have 40GB/48GB/80GB class GPUs and can serve FP8/BF16
your task is code-heavy
you care more about correctness than raw token speed
you want one default model for an internal coding assistant
Choose Qwen 3.6 35B-A3B When Local Hardware Is the Constraint
MoE models still need memory for the weights.
You do not magically load only the active experts but at generation time, active parameters strongly influence compute.
People are trying to cram large MoEs into consumer hardware and getting usable tokens per second.
A low-active-parameter MoE can be a better local trade-off than a smaller dense model, if your memory system can feed it and the quant does not destroy behavior.
Use Qwen 3.6 35B-A3B when:
you want a local coding agent on a 12GB, 16GB, or 24GB VRAM card
you can tolerate careful quantization
you can tune context size instead of blindly maxing it out
you want fast-enough local tool use
you accept that RAM spillover performance depends heavily on memory bandwidth
Also once you spill into system RAM, memory bandwidth becomes king.
DDR3, DDR4, DDR5, PCIe, CPU memory topology, mmap behavior, and offload strategy can matter more than people expect.
This is why two users can claim wildly different tokens per second on the same GPU, where they do not actually have the same system.
Choose Gemma 4 When the Task Is Language, Not Code
Gemma 4 is typically preferred for creative writing, roleplay, translation, multilingual use, explanations, and general chat.
For example, acustomer-support agent, translation assistant, document explainer, internal knowledge-base companion, or product-writing copilot may benefit more from Gemma-style language behavior than from a code-first model.
Gemma 4 family includes dense and MoE models, supports text and image input, long context, more than 140 languages, reasoning, coding/agentic capabilities, and system-role support.
That makes it a serious local candidate even if your primary coding loop stays on Qwen.
Use Gemma 4 when:
the user-facing experience is conversational
translation quality matters
tone and natural phrasing matter
the task is creative or explanatory
you need multimodal document/image understanding
you want a second opinion model for code review summaries, docs, or user-facing release notes
Do not force a coding model to be your product copywriter just because it writes decent Python.
Keep Small Models Around
Small models are useful.
A 0.6B, 4B, 8B, 9B, or 14B model can be the right tool for:
intent classification
routing
short extraction tasks
synthetic labels
log summarization
background summarization
autocomplete for simple internal tools
embedded/offline use
privacy-sensitive edge processing
cheap batch jobs
Running a 35B model for every tiny classification request is bad systems design.
The real stack often looks like this:
small model for routing, cheap extraction, and summaries
Qwen coding model for repo edits and tool use
Gemma model for human-facing language
cloud fallback only for tasks that exceed local capability
Remember that this is a product architecture.
The Local Agent Reference Architecture
Let’s get back to our local agent stack for a second.
The API boundary matters because it decouples the product from the model runner.
OpenCode supports local models through llama.cpp and other OpenAI-compatible providers. Cline also supports OpenAI-compatible providers, including local model servers such as Ollama and LM Studio, and any endpoint that behaves like the OpenAI API. Qwen-Agent can connect to your own deployed OpenAI-compatible service through vLLM or SGLang.
This means the agent harness can stay stable while you test model backends.
Quantization: Measure Behavior.
The general perception about quantization is following:
A garbage quant of a massive model is a bagillion times better than your precious micro-models anyway.
That is sometimes true enough to be tempting but it is not reliable enough to be a rule.
Quantization is not just compression because it changes behavior.
The lower you go, the more likely you are to damage:
world knowledge
numerical stability
tool-call formatting
code syntax
instruction following
long-context recall
stopping behavior
multilingual quality
You can think of the practical split:
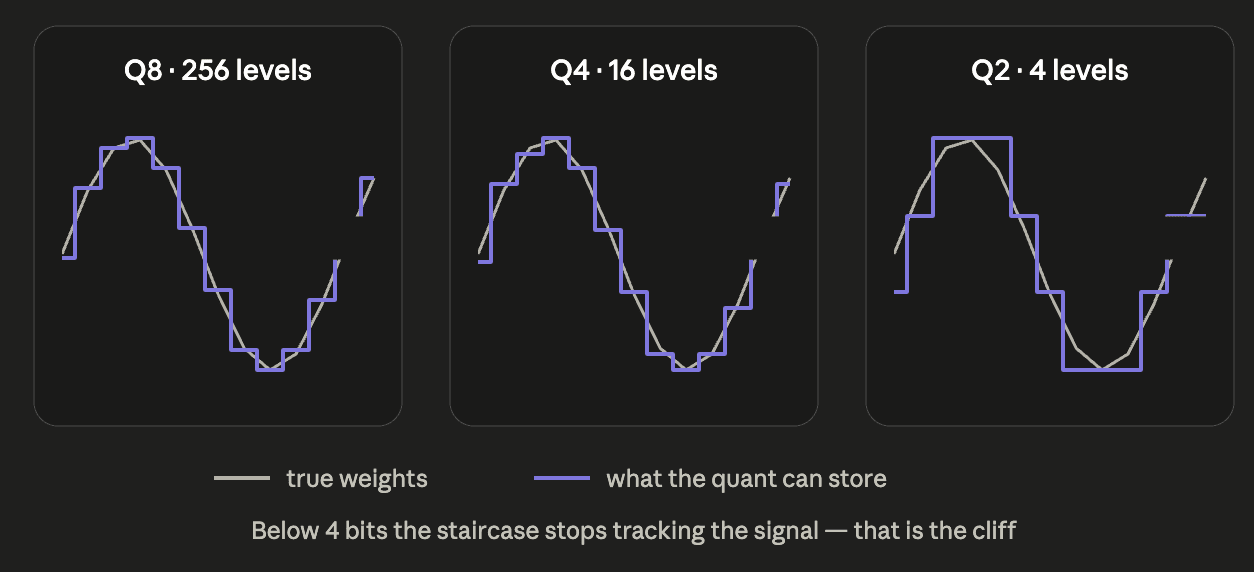
Q4 is often the minimum sane default for serious work.
Q5 is better when you can afford it.
Q8 is comfortable but may be too heavy.
Q3 can be acceptable for some tasks.
Q2 can be useful in constrained setups or very large models, but it is not a default for reliable coding agents.
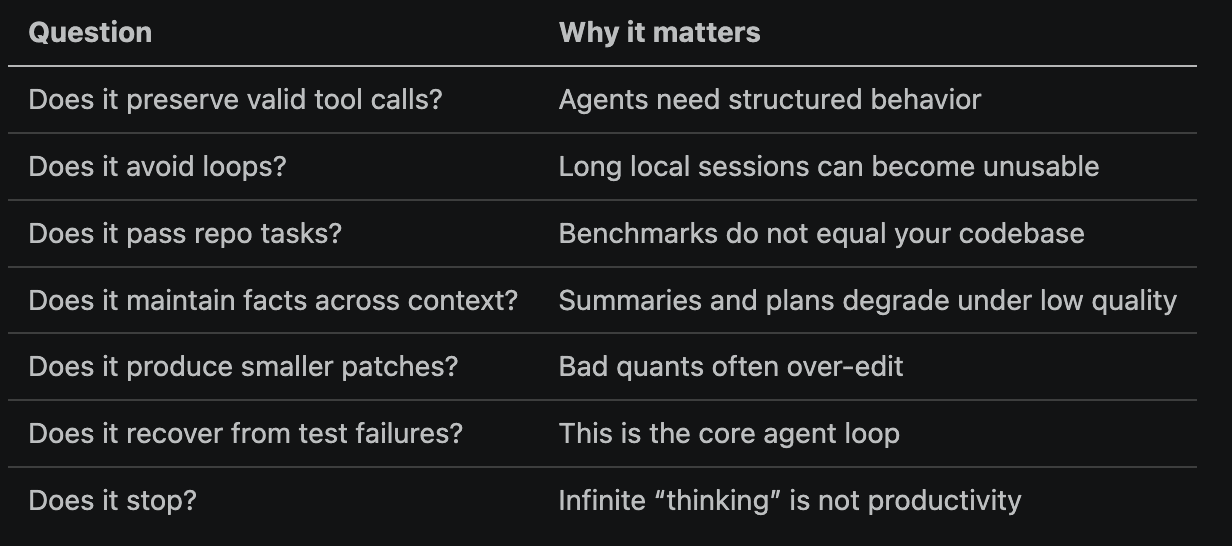
The mistake is evaluating quants by whether they load but the correct evaluation is:
A smaller high-quality model can beat a damaged large quant for short tasks, strict JSON, low latency, and classification.
A low-quant larger model can beat a tiny model for reasoning-heavy tasks.