Fable 5 Is COMPLETELY Wasted on Most Developer Workflows
Agent Native•July 8, 2026
Most developers are using Fable 5 completely wrong.
They use it like a glorified task runner: paste in a task, wait for the model to grind through it, commit whatever comes back, and move on.
That workflow can produce useful output, but it’s also the fastest way to burn Mythos-tier tokens while capturing almost none of the value that actually compounds.
Anthropic just extended Claude Fable 5 access across all paid plans through July 12.
You should separate using the model from actually building with it, because those are not the same.
If your workflow begins and ends with a single expensive run, you are paying premium prices for disposable output.
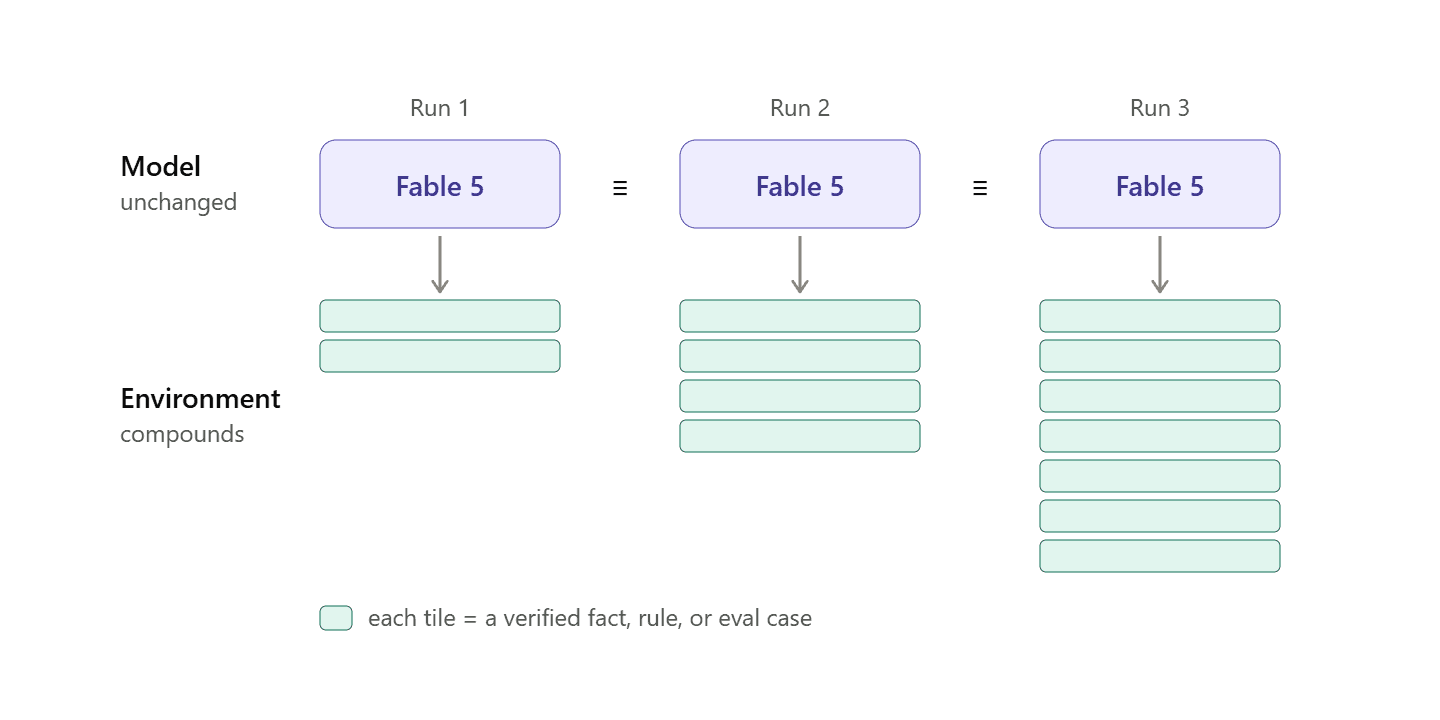
A self-improving agent system gets better because everything around the model gets better, i.e., the environment compounds.
You should treat Fable 5 like the core engine inside a system that remembers, evaluates, routes, and hardens over time, each run makes the next run cheaper, sharper, and more reliable.
That is where the compounding value is, and most people are leaving it on the table.
Let’s dive in.
The core architecture
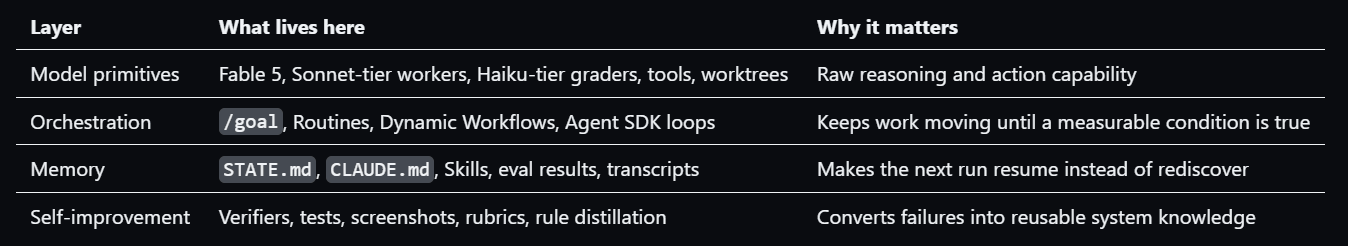
The stack is simple enough to draw on a whiteboard.
Start by making one loop compound.
The loop is:
Read memory.
Do the work.
Verify the artifact with an independent checker.
Distill the lesson.
Write it back into memory and Skills.
The agentic loop is simply context gathering, action, and verification.
The important engineering decision is what you persist between runs.
If nothing is persisted, every session is a cold start.
Editor’s note: To celebrate reaching 10,000 community members on Medium, who relentlessly design, ship, and iterate on agents every day, we’re also making the full repository available for free, which is part of our Agent Foundry program.
Fable 5 is the orchestrator
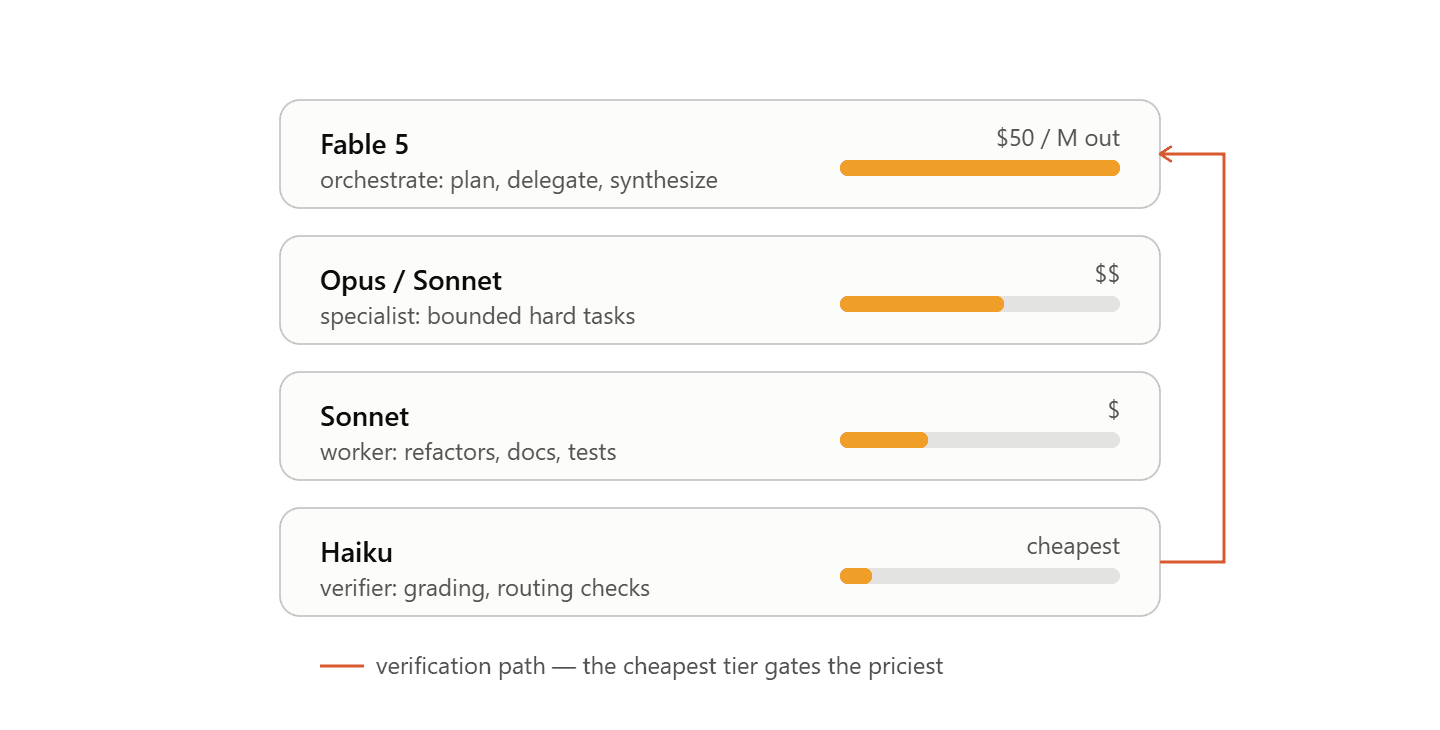
Fable 5 is the orchestrator and the judge is cheaper than the work it judges.
Output tokens cost 5× input ($10 in, $50 out), so generation is where the bill explodes.
You reserve Fable for the plan and the ambiguity, fan trivial work to cheap tiers, and put a Haiku-tier grader in charge of gating Fable’s output.
Fable 5 should decide the plan, split work, interpret ambiguous failures, and update memory but it should not spend premium tokens renaming variables or formatting docs.
This is the same design instinct you already use in distributed systems.
You do not put every job on the biggest machine, you put the coordinator on the machine that can reason across the full graph, and you fan out cheaper workers for parallel tasks.
One compounding CI triage loop
Pick a task with a real pass/fail signal.
CI triage is ideal because it has logs, tests, deterministic commands, and a clear done state.
Create STATE.md:
Project memory · payments-api
Verified facts
CI runs Node 22 and PostgreSQL 16.
Integration tests require STRIPE_WEBHOOK_SECRET in the environment.
npm run test:ci is the source of truth for merge readiness.
General rules
Never disable a failing test to make CI green.
Do not edit .github/workflows/* without human review.
Payment and billing changes require a security-review label.
Open failures
2026-07-05: checkout webhook test flakes intermittently.
Hypothesis: event ordering race between webhook receiver and assertion.
Repro: npm run test:ci -- checkout-webhook
Lessons learned
Retry once before labeling a test as deterministic.
When a failure mentions missing webhook secret, classify as environment, not product bug.
Last session
Next: reproduce checkout webhook flake, classify, and either draft a fix or escalate.
Create CLAUDE.md:
Agent instructions
Read STATE.md before changing code.
For CI triage:
Reproduce the failure.
Classify it as env, flake, bug, dependency, or infra.
Fix only deterministic product bugs.
Escalate env, security, and workflow changes.
End every run by updating STATE.md with verified facts, open failures, and lessons.
Do not delete tests. Do not modify billing code without explicit approval.
Now run the loop manually once:
claude --model claude-fable-5
Inside Claude Code:
/goal npm run test:ci passes, STATE.md is updated, and every CI failure is classified with evidence
The /goal command is important.
It is a session-scoped completion condition checked after every turn by a separate small model.
If the goal is not met, Claude continues instead of returning control to you.
This is the smallest practical move from chat to loop.
Add the verifier subagent
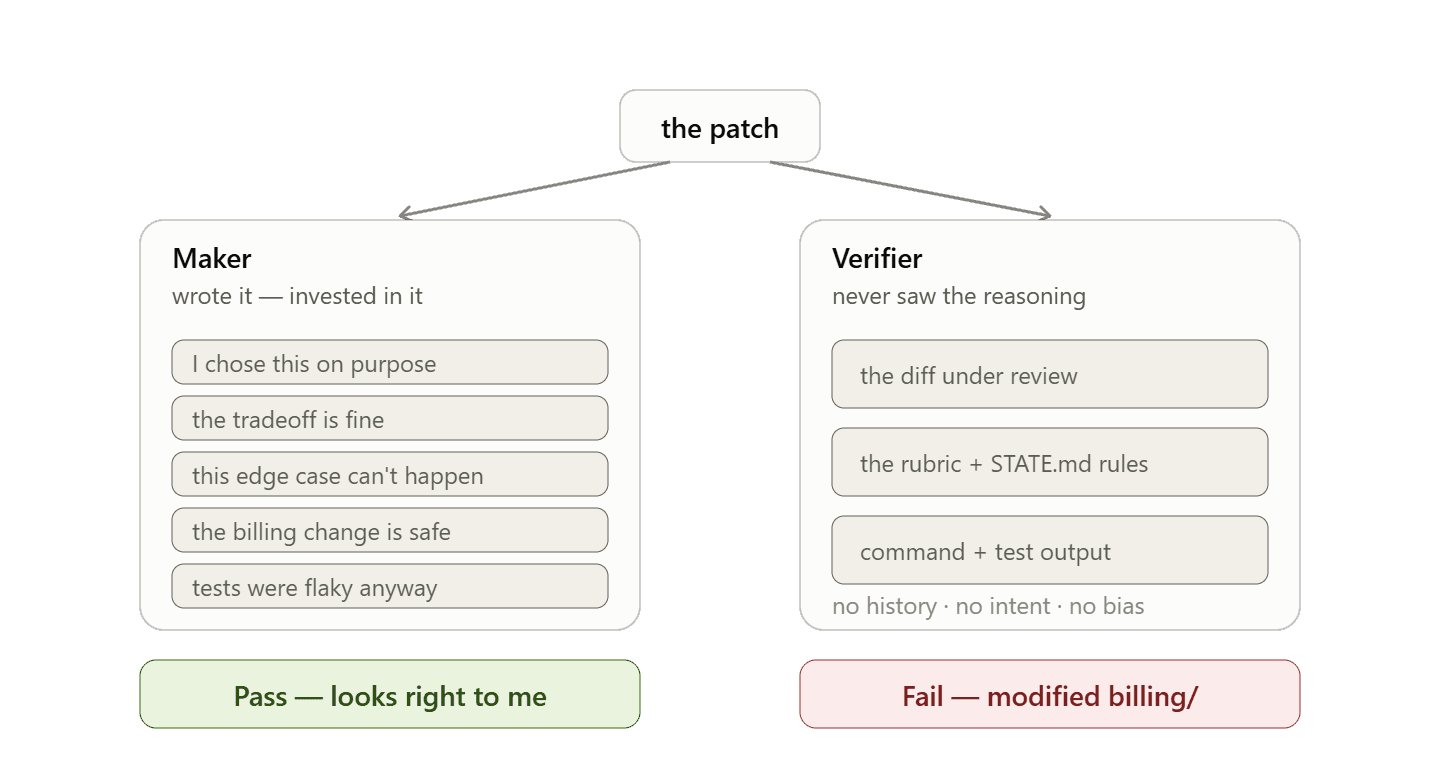
Self-critique is not enough for serious agent systems.
The maker agent has too much context about why it made the change.
A verifier should see the artifact, the rubric, and the command output but it should not inherit the maker’s emotional investment in the patch.
Create .claude/agents/verifier.md:
---name: verifier
description: Independently verifies code changes against tests, rubrics, and STATE.md. Use after implementation and before marking a task done.
model: haiku
allowed-tools: Read, Bash, Glob
You are an independent verifier.
You did not write the patch. Do not defend it.
Check:
Did the requested command pass?
Did the change solve the stated problem without broad unrelated edits?
Did the run update STATE.md with verified facts and lessons?
Did the agent avoid protected files and forbidden shortcuts?
Return one of:
PASS
FAIL_WITH_FIXABLE_GAPS
FAIL_REQUIRES_HUMAN
Include exact evidence: command, file path, failing assertion, or missing state entry.
Claude Code supports custom subagents with focused prompts, tool restrictions, and model selection.
Use it like this:
Use the verifier subagent to check the CI triage result. It must inspect the patch, run the relevant tests, and confirm STATE.md was updated.
Do not treat a passing test suite as the whole verifier.
Passing tests answer “does the code run?” but they do not answer “did the agent modify the wrong subsystem?” or “did it forget to write the lesson back?”
Make Skills compound
A Skill is procedural memory.
It is where you put reusable know-how that should travel across sessions and projects.
Create .claude/skills/ci-triage/SKILL.md:
---name: ci-triage
description: Classify CI failures, draft safe fixes, and escalate risky cases.
CI triage skill
Classification rules
Class
Signal
Action
env
missing secret, missing service, bad runner variable
escalate
flake
passes on retry without code change
document and file issue
bug
deterministic failure tied to source change
draft fix
dependency
failure starts after version bump
draft rollback or compatibility patch
infra
timeout, OOM, network, runner instability
escalate
Known failure modes
webhook-race: checkout tests fail when webhook delivery and assertion overlap.
Fix pattern: wait for persisted event before asserting downstream state.
missing-webhook-secret: integration test fails before app boot.
Action: mark env, do not change product code.
Anti-patterns
Do not skip or delete failing tests.
Do not change CI workflow files without human approval.
Do not touch payment authorization logic without security review.
State contract
Every run must update STATE.md with:
classification
evidence
command output summary
fix drafted or escalation reason
lesson learned if a new failure mode was confirmed
Skills are powerful because they can include instructions and code, which also means they require trust and review.
Treat Skills like code, e.g., review them, version them, add owners and do not install random Skills into production automation without reading them.
The compounding rule is simple: when the verifier confirms a new failure mode, write it into the Skill.
Dynamic Workflow: when one loop is not enough
A plain /goal is perfect when one agent can iterate against one objective.
Use a Dynamic Workflow when the task has branches.
Examples:
Run three independent failure investigations in parallel.
Assign one verifier per changed subsystem.
Test multiple migration strategies in separate worktrees.
Synthesize evidence from workers into one final decision.
Workflow tool is a dynamic workflow script that can orchestrate subagents with primitives like agent(), parallel(), and pipeline().
A CI compounding workflow could look like this:
Code
typescript
export const meta = {
name: "ci-compound",
description: "Classify CI failures, draft safe fixes, verify independently, and update memory.",
phases: ["read-state", "fanout", "verify", "distill"]
};

export default async function workflow({ agent, parallel, pipeline, phase, args }) {
await phase("read-state");

const state = await agent("state-reader", {
  prompt: "Read CLAUDE.md, STATE.md, and the latest CI logs. Return failure clusters as JSON."
});

await phase("fanout");

const fixes = await parallel(
  state.failureClusters.map((cluster) =>
    agent(`triage-${cluster.id}`, {
      prompt: `Investigate this failure cluster in an isolated worktree. Classify it and draft a safe fix if allowed: ${JSON.stringify(cluster)}`
    })
  )
);

await phase("verify");

const verdicts = await parallel(
  fixes.map((fix) =>
    agent(`verify-${fix.id}`, {
      prompt: `You are an independent verifier. Check this fix, run relevant tests, and return PASS/FAIL with evidence: ${JSON.stringify(fix)}`
    })
  )
);

await phase("distill");

return agent("memory-writer", {
  prompt: `Update STATE.md and the ci-triage Skill using only verified lessons: ${JSON.stringify(verdicts)}`
});
}
The key is explicit orchestration.
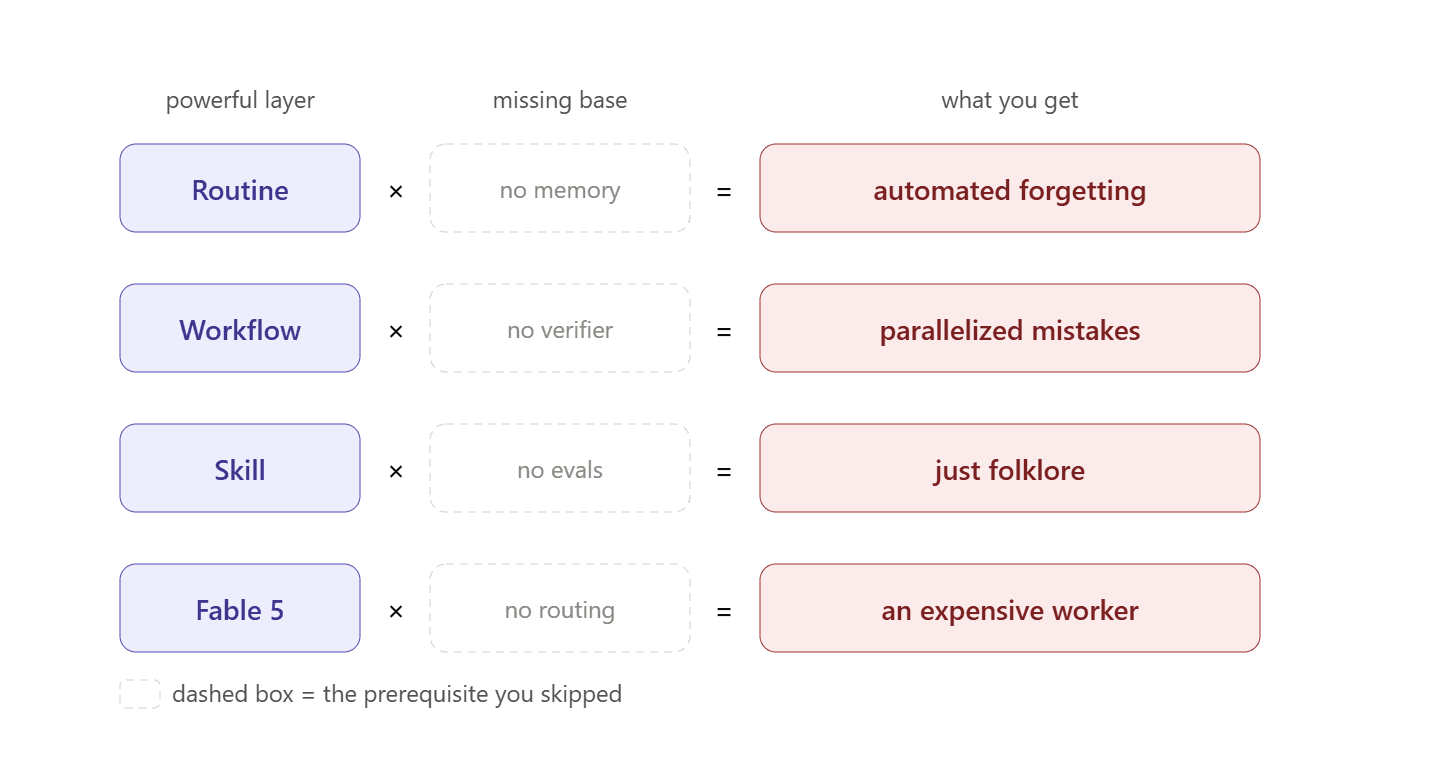
Parallel work should be parallel, verification should be independent and memory writing should happen only after evidence exists.
Worktrees are the isolation primitive
Once multiple agents can write files, shared checkout state becomes dangerous.
This is boring engineering and that is exactly why it works.
Routines: make the system run when you are not watching
A compounding system needs triggers.
Claude Code Routines can run on schedules, API calls, and GitHub events.
Each run creates a new session that you can inspect later, and API triggers expose a /fire endpoint protected by a bearer token.
A useful first routine:
/schedule weekdays at 7am, run CI triage compounding for the payments-api repo.
Read STATE.md and the ci-triage Skill.
Run the latest failing CI suite.
Classify failures.
Draft safe fixes on claude/ branches.
Use verifier subagent before marking anything complete.
Update STATE.md and post a digest.
This is where the system starts to behave like an engineering process.
Safety boundary: design fallback as a first-class path
Fable 5 is not Mythos 5 without constraints.
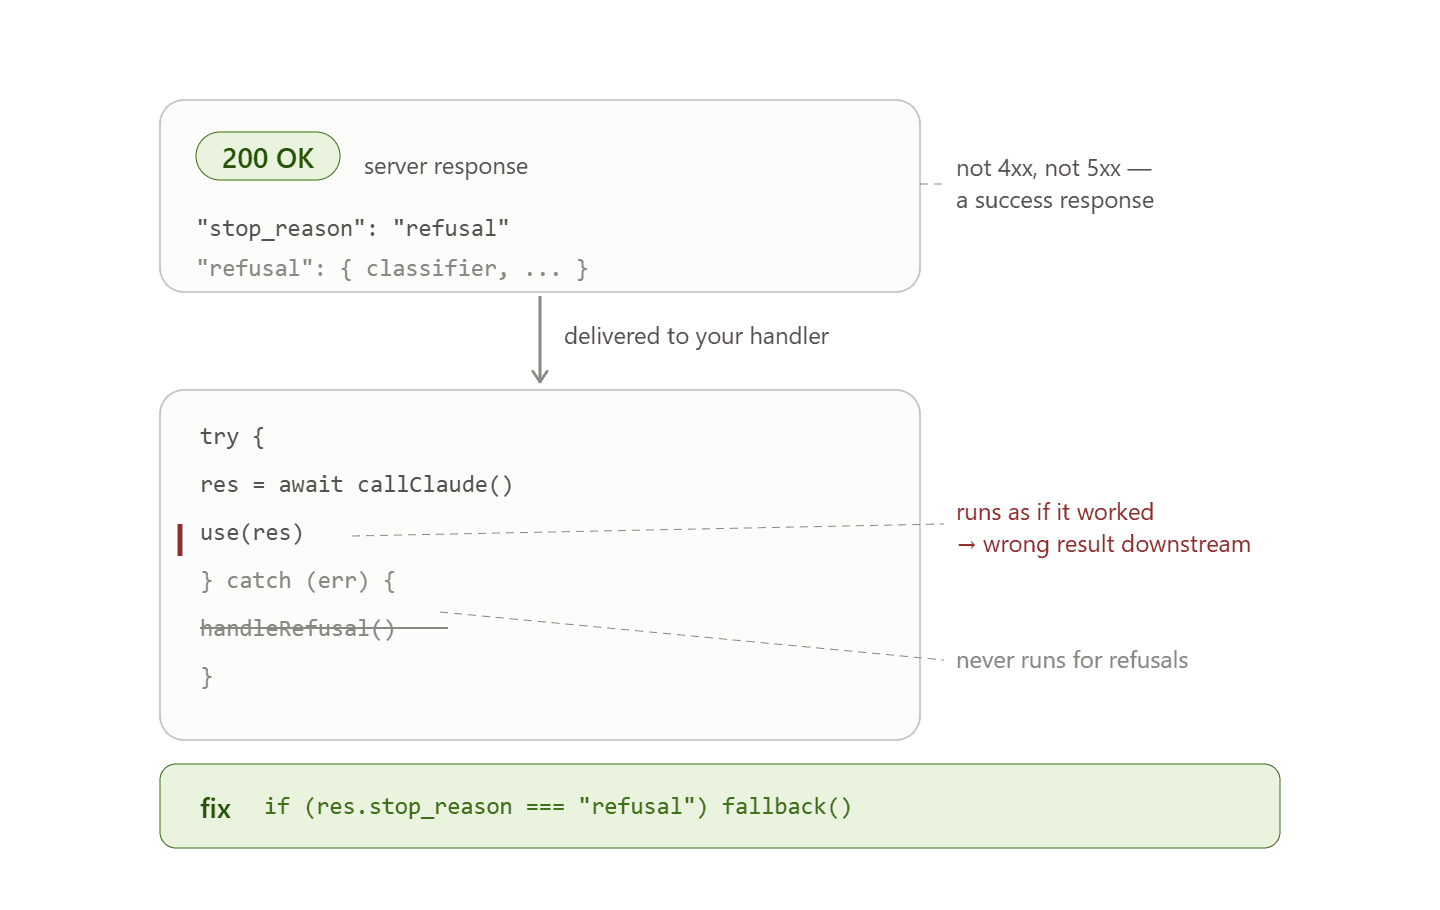
Fable 5 can return stop_reason: "refusal" as a successful HTTP 200 response, not an HTTP error, and that integrations should plan for refusal handling, fallback, and billing behavior.
Refused requests can usually be retried on another Claude model through server-side fallback, SDK middleware, or manual retry.
That means your agent loop needs code like this:
Code
yaml
async function runWithFallback(task: string) {
const result = await callClaude({
  model: "claude-fable-5",
  prompt: task
});

if (result.stop_reason === "refusal") {
  await appendState({
    type: "model_refusal",
    classifier: result.refusal?.classifier,
    taskSummary: summarize(task),
    nextAction: "retry_on_opus_or_escalate"
  });

  return callClaude({
    model: "claude-opus-4-8",
    prompt: `Handle this task within policy. If still unsafe or ambiguous, escalate.\n\n${task}`
  });
}

return result;
}
A refusal is state and it belongs in STATE.md or your run database because classifier behavior affects future routing.
Also check data retention before routing sensitive data through long-running routines.
Fable 5 and Mythos 5 carry 30-day data retention and are not available under zero data retention.
The compounding contract
The whole system depends on a contract:
No run is complete until it leaves the next run better prepared.
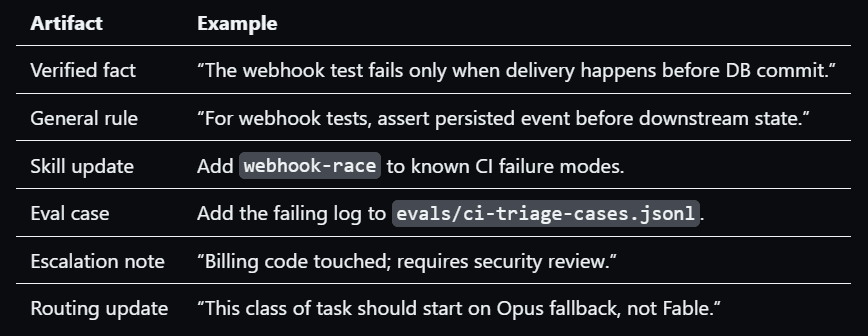
Make that concrete.
Every run must produce at least one of these:
If a run only produces a chat answer, it did not compound.
What to build today
Add these in order:
STATE.md with verified facts, rules, failures, lessons, and last session.
A verifier subagent with read-only tools.
A /goal condition for one real workflow.
A Skill that gets updated after confirmed failures.
A hook or script that blocks protected files.
A Dynamic Workflow only after the simple loop proves valuable.
A Routine only after the workflow has safe permissions and useful logs.
The product is the loop you build around the model.
Fable 5 makes longer, more ambitious loops practical, which is enough to build a system that compounds.